g++ -std=c++14 hello-world.cpp -o hello-world
./hello-world
Hello worldPHS 7045: Advanced Programming
These slides are adapted from a lecture by George G. Vega Yon, Ph.D. (link).
Learning objectives:
We will need a compiler:
You profiled your code and vectorized what you could. It’s still slow. Now what?
You already rely on C++ every day:
. . .
Learning C++ means you can write the fast part yourself and read the source of the packages you depend on.
The program
library() in R. This is part of the standard library.
cout function from std (standard library). Also, the code ends with semicolon (;).
We can use g++ to compile the code (-std=c++14 is the C++14 standard):
g++ -std=c++14 hello-world.cpp -o hello-world
./hello-worldHello worldCompiler: a program that translates your .cpp source code into machine code your CPU can run directly.
hello-world). That is a large part of where the speed comes from.Standard: the official version of the C++ language, revised every few years.
-std=c++14 tells the compiler which version of the language to read your file as. Code using a C++17 feature will not compile under -std=c++14.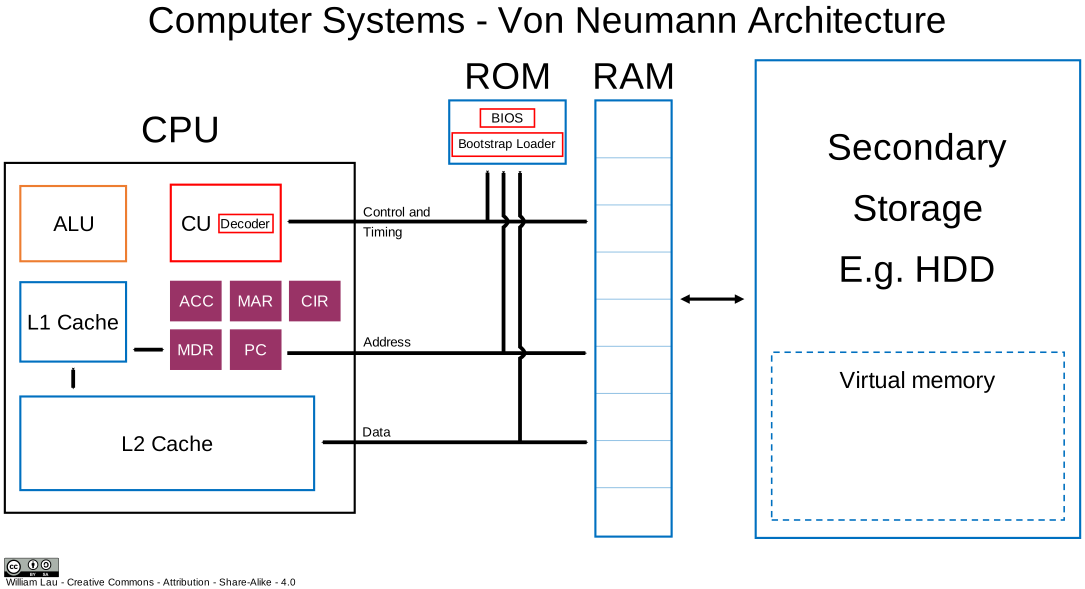
Diagram by William Lau, Wikimedia Commons, CC BY-SA 4.0.
A program is, in the end, a sequence of machine-code instructions the CPU can fetch and execute.
hello-world.cpp. It cannot read R code either.-std=c++14) tells it which version of the language to read your file as.Interpreter: a program that reads your code and carries out what it says, while your program runs.
R on your laptop is an executable written mostly in C, compiled once by whoever built it — just like hello-world was.sqrt(2), you hand that program a piece of text. It works out what the text means and calls the C function that does the square root.> prompt is the interpreter, sitting there waiting for its next instruction.. . .
A compiler is a translator: it turns the whole book into another language once, and you read the translation. An interpreter is a performer: it is handed the script and acts it out, line by line, every time.
R is a program written in C, compiled once, long before you started. Your script is data to it.s + sqrt(i), on every pass R must look up what sqrt and + mean right now, check the types of s and i, and allocate a place for the result — before doing the one instruction of actual arithmetic.. . .
The interpreter never leaves: the arithmetic is one CPU instruction, and everything around it is a hundred more.
R — interpreted
s <- 0
for (i in 1:n)
  s <- s + sqrt(i)
Per iteration, the interpreter must:
sqrt and + mean right now,s and i,All of that, n times.
C++ — compiled
double s = 0.0;
for (int i = 1; i <= n; ++i)
  s += std::sqrt((double) i);
The compiler settled all of that once, before the program ran:
s is a double, i is an int — fixed, no checking,sqrt is one machine instruction,The CPU just adds numbers.
. . .
The arithmetic itself is equally fast in both. R’s + and sqrt are C functions inside the R binary, and they end up at the very same CPU instruction the C++ version uses. The difference is never the math — it is everything R has to do around the math, n times over.
With n = 10,000,000 on my laptop:
| time | |
|---|---|
R (for loop) |
~0.145 s |
C++ (g++ -O2) |
~0.008 s |
g++ vs clang++Both are C++ compilers: same language, same standards, (mostly) the same flags.
g++ — GNU Compiler Collection (GCC). Default on Linux and with Rtools on Windows.
clang++ — LLVM’s compiler. Default on macOS, shipped with Xcode command line tools.
The commands are interchangeable for everything in this lecture:
g++     -std=c++14 hello-world.cpp -o hello-world
clang++ -std=c++14 hello-world.cpp -o hello-world
g++ vs clang++ (cont’d)Careful on macOS: g++ is usually just a symlink to clang++. Check with
g++ --versionIf it says “Apple clang”, you are using clang, no matter what you typed.
Practical differences you may hit:
g++; on macOS clang needs libomp installed separately (relevant next week for parallel computing).For R packages, you do not choose directly: R uses whatever is set in ~/.R/Makevars / R CMD config CXX.
system("R CMD config CXX")Download the program here.
#include<iostream> // To print
#include<vector>   // To use vectors

int main() {

  // Defining the data
  std::vector< double > dat = {1.0, 2.5, 4.4};

  // Making room for the output
  double ans = 0.0;

  // Looping through the data
  for (size_t i = 0; i < dat.size(); ++i)
    ans = ans + dat[i];

  ans = ans/dat.size();

  // Print out the value to the screen
  std::cout << "The mean of dat is " << ans << std::endl;

  // Returning
  return 0;

}++i).To compile it, run the following command:
g++ -std=c++14 means.cpp -o means
./means
The mean of dat is 2.63333We can leverage modern C++ to make the code shorter with std::accumulate()
#include<iostream> // To print
#include<vector>   // To use vectors
#include<numeric>  // To use the accumulate function

int main() {

  // Defining the data
  std::vector< double > dat = {1.0, 2.5, 4.4};

  // Making room for the output
  double ans = std::accumulate(
    dat.begin(), dat.end(), 0.0
    );
  ans /= dat.size();

  // Print out the value to the screen
  printf("The mean of dat is %.2f\n", ans);

  // Returning
  return 0;

}numeric library that has the accumulate functionstd::accumulate function sums the elements of the vector.To compile it, run the following command:
g++ -std=c++14 means2.cpp -o means2
./means2
The mean of dat is 2.63Here are some differences between C++ and R:
| Feature | C++ | R |
|---|---|---|
| Execution | Compiled | Interpreted |
| Type explicit? | Yes | No |
| Index starts at | 0 | 1 |
for loop |
for (int i = 0; i < n; ++i) |
for (i in 1:n) |
| Line ending | “;” |
“\n” (implicit) |
Compiled: translated to machine code before running — faster execution. Interpreted: another program reads and carries out your code as it runs — interactive, but slower.
Type explicit: in C++, we always declare the type of the variables. In R, we don’t need to.
Adapted from W3 Schools:
int my_num           = 5;       // Integer (whole number)
float my_float_num   = 5.99;    // Floating point number
double my_double_num = 9.98;    // Floating point number
char my_letter       = 'D';     // Character
bool my_boolean      = true;    // Boolean
std::string my_text  = "Hello"; // String
Vectors in C++ are similar to atomic vectors in R — all elements share one type:
std::vector< int > my_vector = {1, 2, 3, 4, 5};
std::vector< std::string > my_str_vector = {"a", "b", "c"};
std::vector< std::vector< int > > my_matrix = {{1, 2}, {3, 4}};How much memory each type takes, and what fits in it:
| Data type | Size | Description |
|---|---|---|
bool |
1 byte | Stores true or false |
char |
1 byte | A single character/letter/number, or ASCII value |
int |
2 or 4 bytes | Whole numbers, no decimals |
float |
4 bytes | Fractional numbers; ~6–7 decimal digits |
double |
8 bytes | Fractional numbers; ~15 decimal digits |
Adapted from W3 Schools.
In R you never see this: every number is a double (8 bytes) unless you work at it, and a “scalar” is really a length-1 vector with a header.
In C++ you choose, and the choice has consequences:
double vs float: 8 vs 4 bytes — half the memory, but only ~7 digits of precision.ints is 400 MB; as doubles, 800 MB.“2 or 4 bytes” for int is not a typo: sizes are implementation-defined. Check rather than assume:
std::cout << sizeof(int) << std::endl; // bytesSmaller types also mean less data to move around: 1 million doubles is 8 MB, but only 4 MB as floats. For big arrays scanned repeatedly, that can matter more than the arithmetic itself.
. . .
This is a later concern. float buys speed by giving up precision (~7 digits vs ~15) — rarely a good trade in statistics. Default to double; worry about bytes when profiling says to.
Vectors make life easier, avoiding the need to manage memory.
Vectors store contiguous memory, allowing for fast access.
Vectors have many methods to manipulate the data:
my_vector.push_back(6); // Add an element
my_vector.pop_back();   // Remove the last element
my_vector.size();       // Number of elements
my_vector[0];           // Access the first element
my_vector.at(0); // Access the first element (safer)Looping through vectors can be done in different ways:
// Suppose we have this:
std::vector< int > my_vector = {1, 2, 3, 4, 5};

// Typical loop
for (int i = 0; i < my_vector.size(); ++i) {
  std::cout << my_vector[i] << std::endl;
}

// Using vector's iterators (begin and end)
// and the auto keyword
for (auto i = my_vector.begin(); i != my_vector.end(); ++i) {
  std::cout << *i << std::endl;
}

// Using range-based for loop (with the auto keyword)
for (auto i: my_vector) {
  std::cout << i << std::endl;
}i is an iterator (pointer-like), and *i is the value it refers to.auto: “compiler, work out the type for me” — here std::vector<int>::iterator and int. Deduced at compile time; the variable still has one fixed type.auto i gives you a copy. Use auto & i to modify the vector, and const auto & i to read big objects without copying them.Types can go accompanied by keywords:
const: the value of x cannot be changed. Trying to modify it will result in a compilation error.
x is passed by copy (not ideal for large objects). It can be modified inside the function.
x is still a copy, but it cannot be modified.
&: passing by reference. Ideal for large objects. It can be modified.
const &: passing by reference, but cannot be modified.
*: passing by pointer. The value can be modified. NOT RECOMMENDED FOR C++
The following code (pointers.cpp) illustrates how these keywords work:
#include <cstdio> // For the std version of printf

void set_x_copy(int x, int y) {x = y;};
void set_x(int * x, int y) {*x = y;};
void set_x_ref(int & x, int y) {x = y;};
// This would generate an error
// void set_x_ref(const int & x, int y) {x = y;};

int main() {

    int x = 0;

    set_x_copy(x, 3);
    std::printf("x = %d\n", x);
    set_x(&x, 2);
    std::printf("x = %d\n", x);
    set_x_ref(x, 1);
    std::printf("x = %d\n", x);

    return 0;

}set_x_copy: the x inside the function is a new int at a different address, initialised from the caller’s value. x = y writes there, the caller’s x is never touched — and it is destroyed on return.set_x: x is a pointer — its own variable, whose value is an address. &x at the call site means “the address of x”; *x = y means “write y to whatever lives at that address”.set_x_ref: x is a reference — an alias, a second name for the caller’s memory, with no storage of its own. x = y writes straight to it.x, not &x. Only the pointer version shows up at the call site. Here the names help you, but in real code (update(v)) nothing at the call tells you whether v can be modified: you have to read the signature.const int & x the compiler refuses to build it: you promised not to modify what x refers to.To compile and run the code:
g++ -std=c++14 pointers.cpp -o pointers
./pointers
x = 0
x = 2
x = 1Picture main’s x sitting at address 0x100, holding 0. Each call does something different with it:
set_x_copy(int x, int y) — the parameter x is a brand-new int at a different address (say 0x200), initialised with a copy of the caller’s value. x = y writes 3 to 0x200; nothing at 0x100 is touched, so main’s x is still 0. On return, the parameter is destroyed.
set_x(int * x, int y) — the parameter x is a pointer: a separate variable (at, say, 0x300) whose value is an address. &x at the call means “the address of x”, so the caller passes 0x100 and the parameter holds 0x100. *x means “the thing at the address stored in x”, so *x = y writes 2 to 0x100.
set_x_ref(int & x, int y) — the parameter x is a reference: an alias, a second name for the same memory at 0x100, with no storage of its own. x = y writes 1 straight to 0x100.
x, not &x. Only the pointer announces itself at the call site, so for the other two you must read the signature to know what will happen.. . .
std::vector<double> with a million elements copies 8 MB; a reference or a pointer copies an address (8 bytes).const & gives you both: no copy, and a promise not to modify.Example class (you can download the file here):
1#ifndef PERSON_HPP
#define PERSON_HPP

#include<string>
#include<iostream>

class Person {
2private:
    std::string name;
    int age;
    double height;

3public:
  // Constructor
4  Person(std::string n, int a, double h) {
    name = n;
    age = a;
    height = h;
  };

  // Default constructor
  Person() : name("Unknown"), age(0), height(0.0) {};

  // Destructor
5  ~Person() {
    std::cout <<
6      this->name + " destroyed" <<
      std::endl;
  };

  // Getters and setters
7  std::string get_name() { return name; };
  void set_name(std::string n) { name = n; };
};

#endif#ifndef + #define + #endif is the include guard. Avoids multiple inclusions.
this->.
Using the class (you can download the file here):
#include<string>
#include<iostream>
#include "person.hpp"

int main() {
  Person p1; // Default constructor
  Person p2("John", 30, 1.80); // Other constructor

  std::cout << p1.get_name() << std::endl;
  std::cout << p2.get_name() << std::endl;

  return 0;
}
Compiling and executing the program:
g++ -std=c++14 person.cpp -o person
./person
Unknown
John
John destroyed
Unknown destroyedNotice that the destructor is called when p1 and p2 go out of scope (in reverse order).
A good practice is to separate the declaration (bones) from the implementation (meat).
Looking at an extract of the class Person:
// ---------------------------------------
// Declarations: Arguments and data types
// ---------------------------------------
class Person {
private:
    std::string name;
    int age;
    double height;

public:
  // Constructor
  Person(std::string n, int a, double h);

  // Getters and setters
  std::string get_name();
};

// ---------------------------------------
// Implementation: Body of the functions
// ---------------------------------------
inline Person::Person(std::string n, int a, double h) {
  name = n;
  age = a;
  height = h;
};

inline std::string Person::get_name() {
  return name;
};In C++, we can have multiple functions with the same name, but different arguments. This is called overloading.
The compiler will choose the correct function based on the arguments. Both of these functions are valid:
int add_int(int x, int y) {
  return x + y;
}

double add_double(double x, double y) {
  return x + y;
}

float add_float(float x, float y) {
  return x + y;
}
int add(int x, int y) {
return x + y;
}
double add(double x, double y) {
return x + y;
}
float add(float x, float y) {
return x + y;
}In C++, we can use templates to create functions or classes that can work with any data type.
This is useful when we want to create a function that works with int, double, float, etc.
int add(int x, int y) {
  return x + y;
}

double add(double x, double y) {
  return x + y;
}

float add(float x, float y) {
  return x + y;
}Classes can also be templated (defined in template_class.cpp):
#include<iostream>

template<typename T>
class MyAdder {
private:
  T x;
  T y;
public:
  MyAdder(T x, T y) : x(x), y(y) {};

  T add() {
    return x + y;
  };
};

int main() {
  MyAdder<int> a(1, 2);
  MyAdder<double> b(1.0, 2.0);

  std::cout << a.add() << std::endl;
  std::cout << b.add() << std::endl;

  return 0;
}T can be any type.int and double. The compiler will generate two classes during compilation.g++ -std=c++14 template_class.cpp -o template_class
./template_class3
3One way to estimate \(\pi\) is to simulate points in a square and count how many are inside a circle.
The following is an optimized R function to do this:
my_pi_sim <- function(n) {
  xy <- matrix(runif(n*2, min=-1, max=1), ncol = 2)
  message(
    sprintf(
      "pi approx to: %.4f",
      mean(sqrt(rowSums(xy^2)) <= 1) * 4
    )
  )
}

set.seed(331)
my_pi_sim(1e6)
pi approx to: 3.1393Let’s see why this works, and then how to do it in C++.
Draw the unit circle (radius \(r = 1\)) inside the square \([-1, 1] \times [-1, 1]\).
The square has area \(2 \times 2 = 4\). The circle has area \(\pi r^2 = \pi\).
If we pick a point uniformly at random in the square, every location is equally likely, so the probability of landing in the circle is just the ratio of the areas:
\[ P(\text{point inside circle}) \;=\; \frac{\text{area of circle}}{\text{area of square}} \;=\; \frac{\pi}{4}. \]
\[ \hat\pi = 4 \hat p = 4 \times \frac{\text{number of hits}}{n}. \]
That is exactly the * 4 in the R code and the 4.0*pi_approx/n_sims in the C++ code.
Deciding if a point is inside: the point \((x, y)\) is in the unit circle when its distance to the origin is at most 1, i.e. \(\sqrt{x^2 + y^2} \le 1\).
How accurate? Each point is a Bernoulli trial, so \(\text{SE}(\hat\pi) = 4\sqrt{p(1-p)/n} \approx 1.64/\sqrt{n}\). The error shrinks like \(1/\sqrt{n}\): with \(n = 5 \times 10^6\) we get about \(\pm 0.0007\), i.e. roughly three correct decimals. One extra digit costs 100 times more points — which is why we care about speed.
#include <vector>
1#include <random>
2#include <cmath>
#include <cstdio>
int main() {

  // Setting the seed
3  std::mt19937 rng_engine;
  rng_engine.seed(123);

4  std::uniform_real_distribution<double> dist(-1.0, 1.0);

  // Number of simulations
  size_t n_sims = 5e6;

  // Defining the data
  double pi_approx = 0.0;
  for (size_t i = 0u; i < n_sims; ++i)
  {

    // Generating a point in the unit square
    double x = dist(rng_engine);
    double y = dist(rng_engine);

    double d = std::sqrt(
5        std::pow(x, 2.0) + std::pow(y, 2.0)
        );

    // Checking if the point is inside the unit circle
    if (d <= 1.0)
      pi_approx += 1.0;

  }

  printf("pi approx to %.4f\n", 4.0*pi_approx/n_sims);

  return 0;

}std::sqrt/std::pow live in <cmath>, printf in <cstdio>.
std::pow is the power function.
g++ -std=c++14 pi.cpp -o pi
./pi
pi approx to 3.1420The task is to write a class that computes the mean, standard deviation, minimum and maximum of a vector.
The class should be a template class so it can deal with double and int.
You can download the full C++ code here and the header file here:
cat("```cpp\n")
```{.r .cell-code}
cat(readLines("summary.hpp"), sep = "\n")
Warning in readLines("summary.hpp"): incomplete final line found on
'summary.hpp'#ifndef SUMMARY_HPP #define SUMMARY_HPP
#include
template
public: // Constructors Summarizer(const std::vector
// Calculators
double mean() const;
double sd() const;
T min() const;
T max() const;

// Printer
void print() const;
};
template
template
template
template
template
template<> inline void Summarizer
template<> inline void Summarizer
#endif
cat("```\n")
## Details: Declaration of the class

```cpp
template<typename T>
class Summarizer {
private:
    const std::vector<T>* dat = nullptr;
    double n;

public:
    // Constructors
    Summarizer(const std::vector<T> & dat_);

    // Calculators
    double mean() const;
    double sd() const;
    T min() const;
    T max() const;

    // Printer
    void print() const;

};template<typename T>
inline Summarizer<T>::Summarizer(const std::vector<T> & dat_) {
dat = &dat_;
n = dat->size();
};The implementation of the constructor is done outside of the function.
The inline keyword is used to tell the compiler to insert the code in the place where the function is called (more efficient).
Here, data is passed by reference and then the pointer is stored.
template<typename T>
inline double Summarizer<T>::mean() const {
    return std::accumulate(
        dat->begin(), dat->end(), 0.0
        ) / n;
};
The function is declared as const to tell the compiler that the function does not modify the object (the class itself).
The mean function uses the std::accumulate function.
Since dat is a pointer to a vector, we can access the members of dat via the -> operator (otherwise it would be using a . operator).
#include "summary.hpp"

int main() {
    // Some data
    std::vector< double > dat = {1.0, 2.5, 4.4};
    std::vector< int > dat2 = {1, 2, 3, 4, 5};

    // Summarize the data
    Summarizer<double> s_double(dat);
    s_double.print();

    Summarizer<int> s_int(dat2);
    s_int.print();

    return 0;

}
g++ -std=c++14 summary.cpp -o summary
./summarySummary for double data
Mean : 2.63
SD : 1.70
Min : 1.00
Max : 4.40
Summary for int data
Mean : 3.00
SD : 1.58
Min : 1
Max : 5