Performance Optimization
Performance profiling in epiworld focuses on identifying computational bottlenecks in simulation loops and agent update routines. Since the library is header-only and heavily templated, traditional profiling tools that depend on symbol-level separation are less effective. Instead, profiling is typically done through compiler-supported instrumentation (such as -pg with gprof) or runtime sampling tools (such as perf, valgrind, or Intel VTune) when running compiled executables that use the library. For lightweight insight, users can also instrument specific regions in the code with wall-clock timers from the C++ standard library (e.g., std::chrono) to measure step-level performance or to compare different update strategies. Continuous integration pipelines include code coverage reporting through Codecov.
Memory Usage Optimization
Memory management in epiworld emphasizes minimizing allocation overhead and data duplication, which is critical in large-scale agent-based models. The library structures its data around contiguous containers such as std::vector and raw c-arrays, which allow for efficient iteration and relatively predictable cache performance. Dynamic memory use is reduced by preallocating storage for agents, states, and viruses before the simulation begins (or in as broad a scope as possible), based on known population sizes and model configuration.
Because the library is template-based and header-only, most logic is inlined, and data structures are specialized/monomorphized at compile time. This eliminates unnecessary abstraction layers and reduces pointer chasing, improving both speed and memory locality. Models reuse internal buffers and avoid repeated construction of large containers, keeping per-step overhead small even for large populations.
Users running large experiments can further optimize memory by minimizing per-agent state complexity and reusing model objects between runs rather than constructing new ones. Since epiworld does not depend on dynamic memory allocators beyond the standard library, this approach helps maintain predictable memory footprints and avoids fragmentation over repeated simulations.
Parameter Access
Model parameters are stored in a vector, in the order they were added, with a map from each name to its position. A lookup by name (par("Transmission rate"), get_param(), set_param()) searches that map: roughly 20–30 ns per call. That is negligible when it happens once per step, but update functions and virus or tool callbacks run for many agents every day, and there the lookups can add up to a third of the run time.
Code on those paths should read parameters by position instead, at about 2–3 ns per call:
EPI_PAR(model, "name")is the simplest option. It takes a pointer to a model and a string literal, and caches the position in a function-localstatic ParamRef:
ParamRefdoes the same as an object you keep, for example as a member of a class. It resolves the name once per model layout and caches the position, so it gives the right value with any model, including models whose parameters were added in a different order, and it is safe to share between threads.get_param_id()returns aParamId, read withpar_at()and written withset_param_at(). The position is valid for that model and all its copies (including the copiesrun_multiple()makes), because parameters are never removed.
Only positions are cached, never values, so changes made with set_param() (for example by a global event) are seen immediately. Viruses and tools set up with a parameter name (set_prob_infecting("Transmission rate") and similar), new_state_update_transition(), and the built-in models already read parameters this way.
Parallel Execution Strategies
We support parallel execution through OpenMP, which is used to distribute workloads across simulation runs. Currently, OpenMP pragmas are applied when running multiple simulations in parallel.
Users can control the number of threads and scheduling behavior at compile time (via flags such as -fopenmp) or runtime (via environment variables like OMP_NUM_THREADS). Because the core simulation loop avoids global locks and shared-state dependencies, scaling is nearly linear on multi-core systems for sufficiently large populations. Generally, however, users may treat OpenMP as an implementation detail, and not have to worry about it in calling client code.
Due to the structure of the library internally, and where parallel execution can sanely be applied, correctness is relatively simple to attain. Since parallelism techniques, leveraging that of OpenMP, are used primarily to speed up simple accumulatory arithmetic, we do not have to worry about race conditions to such a great degree as one might expect. The combination of template-level inlining and OpenMP parallelism allows epiworld to reach very high throughput—on the order of hundreds of millions of agent-day operations per second on typical hardware.
Cross-Framework Benchmark
The evolving epiworld-benchmark compares eleven epidemic simulation engines on common SEIRH contact-network models. In the scenarios currently covered, the epiworld family is among the fastest, and native epiworld is among the lower-memory implementations.
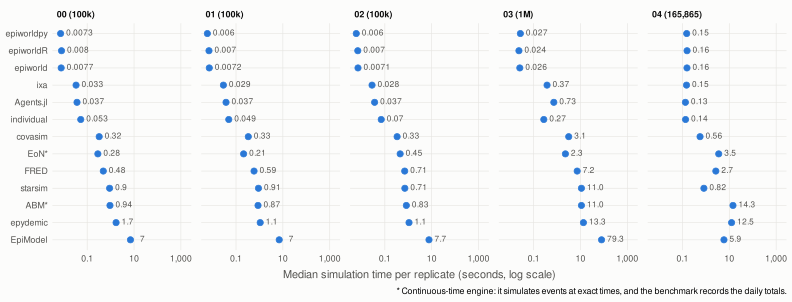
Median simulation time per replicate across the currently implemented scenarios. Source: the benchmark overview.
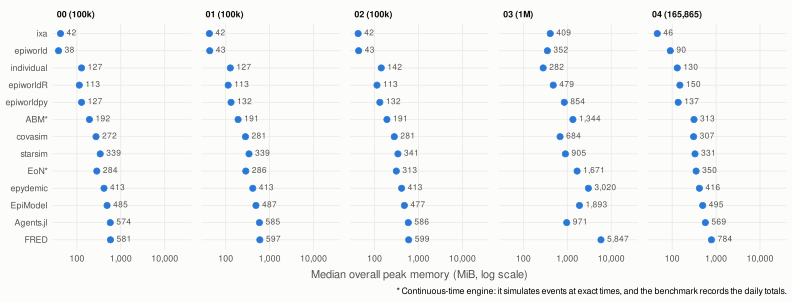
Median overall peak resident memory across the currently implemented scenarios. Source: the benchmark overview.
Work in progress
This comparison is a snapshot of the tested versions, SEIRH workloads, and environment, not a universal ranking. Other engines may perform especially well in scenarios better aligned with their designs. The project is adding engines and scenarios, and welcomes contributions, corrections, and implementation improvements through its scenario guide, issues, and pull requests.
See the benchmark's methods and full results for the model, measurement definitions, and results by scenario.
Benchmarking Methodologies
The examples included in this repository—such as helloworld.cpp and
readme.cpp—serve as informal local benchmarks, reporting elapsed time and
throughput at the end of each simulation. They complement the reproducible
cross-framework benchmark above and provide a convenient way to compare local
compiler flags, thread counts, and versions.
The example 20-transmission-benchmark times the network transmission step: it runs the SEIRH model of the epiworld-benchmark study and two other network models in each transmission mode, and it compiles against older releases too, so versions can be compared side by side (see Push and Pull Transmission).
The example 21-parameter-lookup-benchmark times parameter lookups (see Parameter Access), both per call and inside models whose hot paths call them, such as ModelMeaslesMixing. It also compiles against older releases.
Users can also measure performance externally using tools such as /usr/bin/time,
perf, or custom C++ timing utilities based on std::chrono. Running example
models with controlled parameters and fixed random seeds allows fair comparisons
between compiler flags, thread counts, and machine configurations.
See Also
- Library Architecture — overview of the modular, template-based design that enables many of these optimizations.
- Queueing System — the selective activation mechanism that reduces per-step computation.
- Push and Pull Transmission — sampling transmission from the infectious agents when that is cheaper.
- Reproducibility and
run_multiple— OpenMP-based parallel execution of multiple simulation runs.